Identify inconsistent, matching, and duplicate data across your PostgreSQL tables in just a few clicks.
A guided, read-only analysis tool that works with every PostgreSQL database, from Amazon RDS and Supabase to your own servers.
The PostgreSQL Matching Wizard connects directly to your PostgreSQL database in read-only analysis mode, wherever it is hosted. In a guided, step-by-step flow, you'll generate AI-enhanced match reports that surface inconsistent values, redundant records, and duplicate entries across any of your tables, see the cost before you run, and review the results in an interactive spreadsheet view. Parallel processing delivers maximum performance, even on large tables, and the similarity keys in every report load straight back into PostgreSQL for consolidation with ordinary SQL.
A quick look at the Matching Wizard experience, from connecting to PostgreSQL through reviewing your match report.
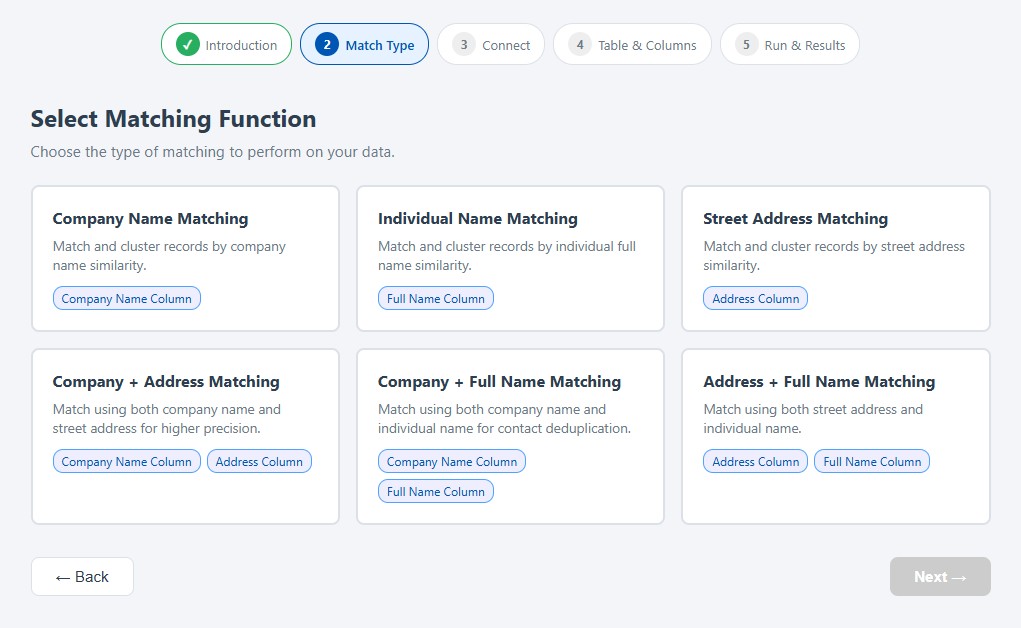
Select the type of matching you want to perform: company names, individuals, addresses, and more.
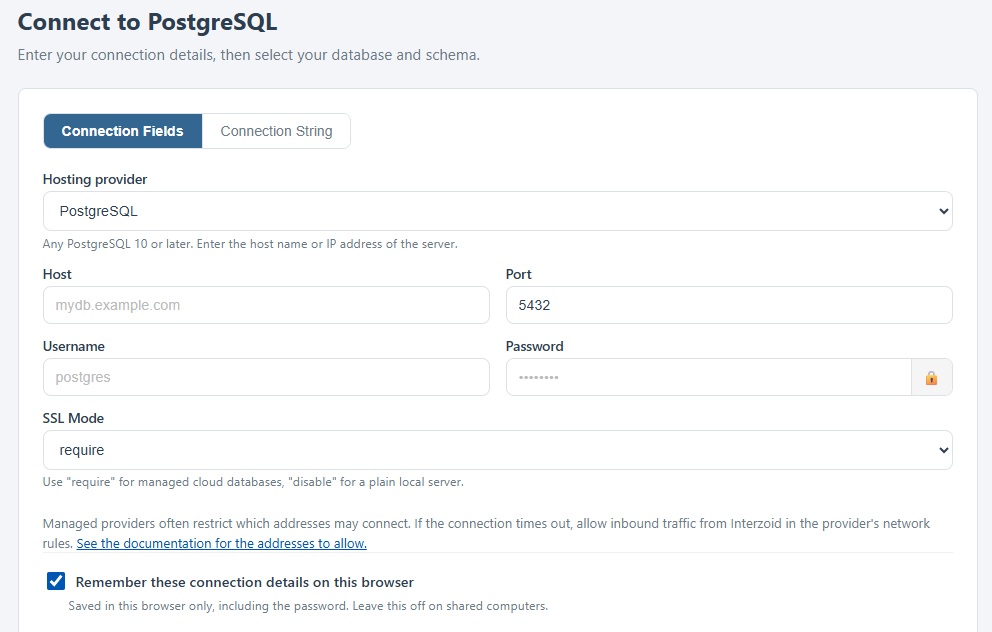
Pick your hosting provider, enter the host and credentials or paste a connection string, and connect in read-only mode over an encrypted connection.
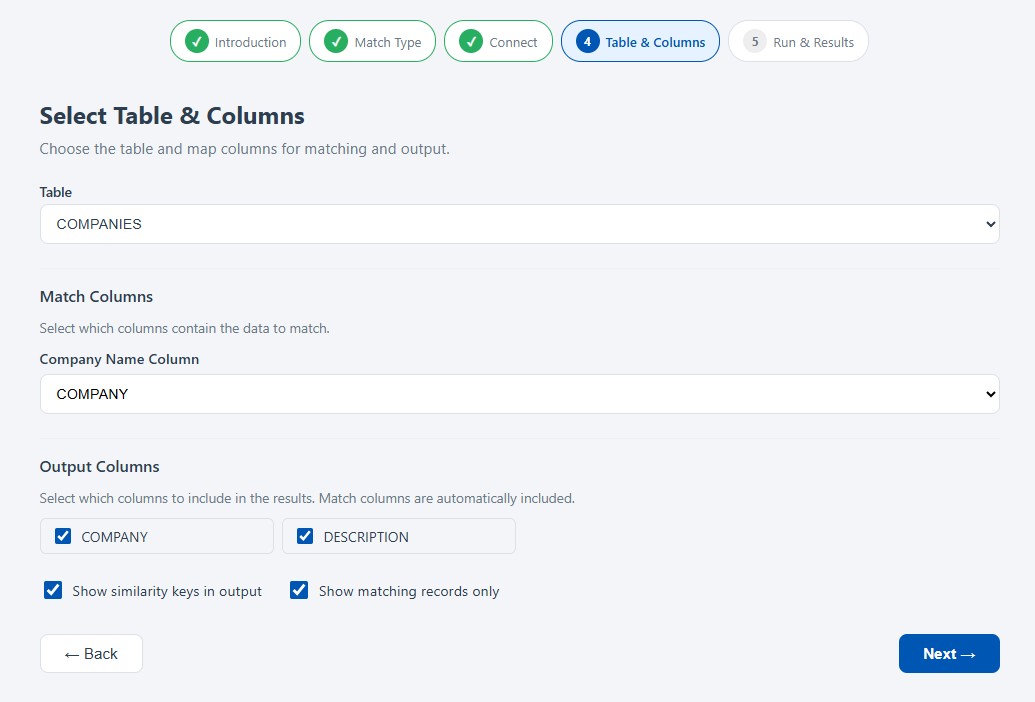
Pick a table and the wizard pre-selects the matching columns, previews the data, and counts the rows so you know the cost before you run.
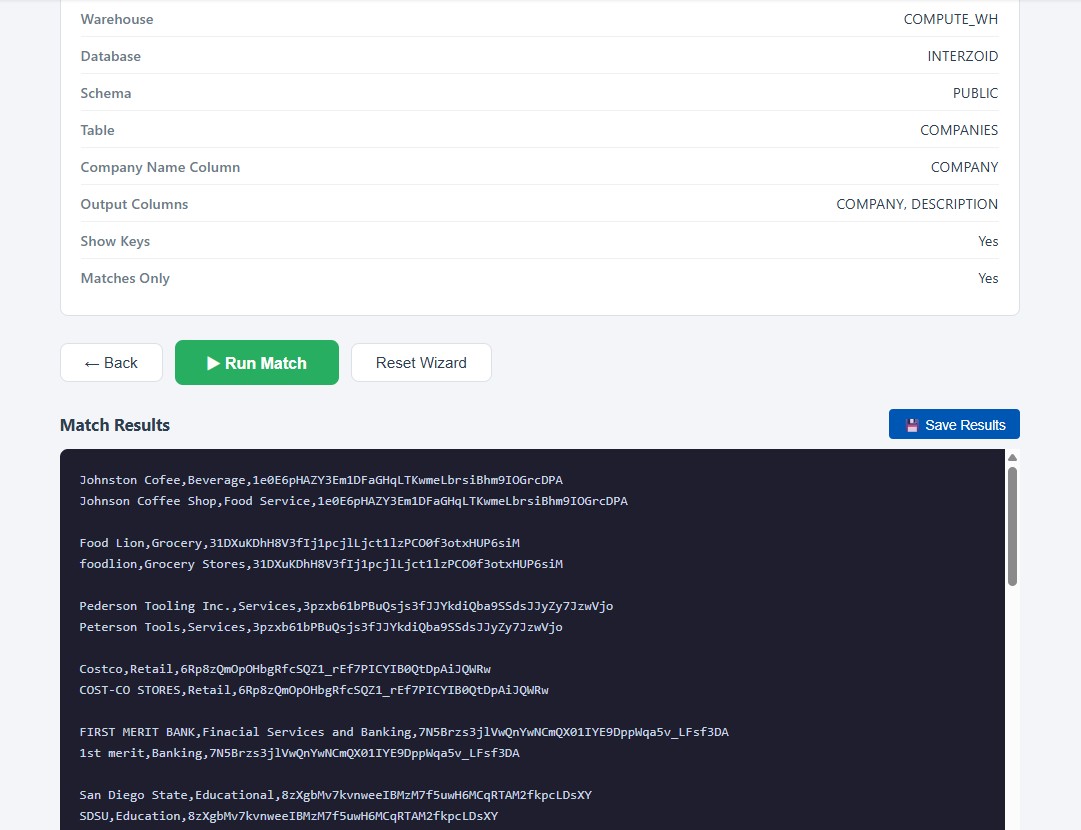
Run the job and explore the match report in a searchable, sortable spreadsheet view with each match group highlighted, then save it as a file.
A guided wizard walks you through connecting to PostgreSQL, choosing your data, and generating a match report. No SQL or scripting required.
The wizard operates entirely in read-only analysis mode. Your PostgreSQL data is never modified, making it safe to run against any of your tables, including production replicas.
Presets for Amazon RDS and Aurora, Supabase, Neon, Azure, Google Cloud SQL, and Heroku fill in the port and SSL settings for you, or paste the connection string your provider gives you. Standard password sign-in over TLS, the same way every major data integration tool connects.
Choose a table and the wizard counts its rows, shows the credit estimate against your balance, and previews the data with your match columns highlighted. No surprises on large tables.
Advanced AI-enhanced similarity algorithms cluster matching records and reveal duplicates and inconsistencies that exact-match queries, LIKE patterns, and trigram searches miss entirely.
Cleaner data means more reliable reporting, better customer insights, accurate joins across systems, and fewer wasted cycles reconciling redundant records.
A multi-threaded, distributed cloud architecture processes large PostgreSQL tables in parallel, delivering match reports fast, even at high data volumes.
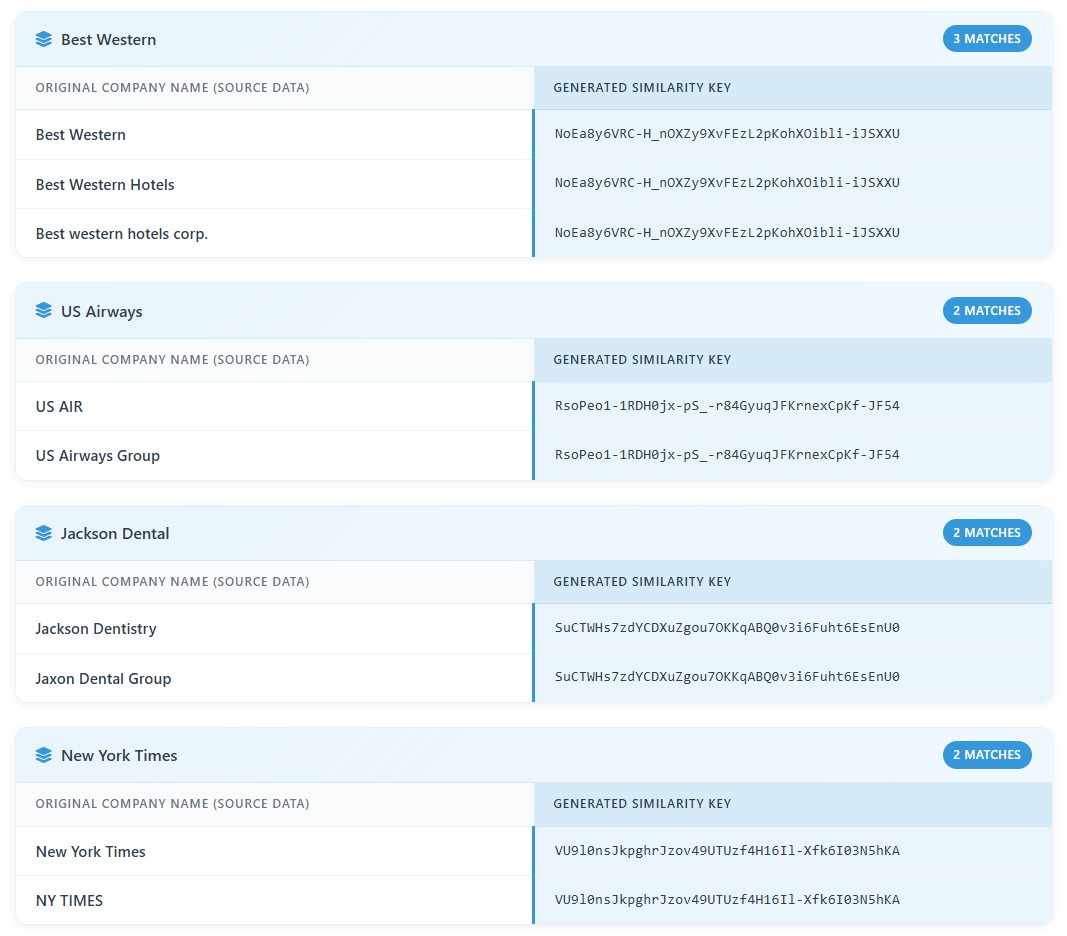
Review results in an interactive spreadsheet view that shades each match group, with search, sorting, and paging across even the largest reports. Save the report as a file, or load the similarity keys back into PostgreSQL and consolidate with a single JOIN.
From connection to match report in three simple steps.
Choose your provider, enter the host and credentials or paste a connection string, and connect. A dedicated read-only role is recommended, and the wizard can remember the connection on your browser.
Choose a table; the wizard pre-selects the columns to match on, previews the data, and shows the row count and credit estimate before you commit.
Run the matching job and explore the AI-enhanced report in an interactive spreadsheet view, with each cluster of matching, duplicate, and inconsistent records highlighted.
See the Matching Wizard in action, generating similarity keys to match company and organization name data directly from within PostgreSQL tables.
Everything you need to get started, from a sample report to step-by-step documentation.
See an example match report for company name data, showing how matching clusters are presented.
View Sample ReportRead the complete documentation covering provider setup, connection, network access, and matching options.
Read the DocsThe same guided matching experience is available for Snowflake accounts, with key-pair authentication built in.
Snowflake Matching WizardIf it accepts a standard PostgreSQL connection, the wizard can read from it. Managed services, serverless platforms, and your own servers, on every current PostgreSQL version.
No extension to install, no agent to deploy, and nothing running inside your database. Point the wizard at a database, schema, and table, and it reads only the columns you select.
Four data types, plus combinations that raise precision when one field alone is too broad
Resolve Acme Corp, ACME Corporation, and Acme Inc. to a single organization, across the legal suffixes, punctuation, abbreviations, and spelling variations that make company names so inconsistent.
Match James Johnston, Jim Johnston, and J. Johnston as the same person, handling nicknames, initials, middle names, and name ordering.
Reconcile 400 E Broadway St with 400 East Broadway Street, resolving directional abbreviations, street type variations, unit designations, and spacing.
Generate similarity keys for other text values, so product names, descriptions, and free-form fields cluster the same way that names and addresses do.
Require two fields to agree at once: organization with address, organization with individual name, or address with individual name. This separates the Dallas branch from the Phoenix branch while still recognizing that both spell the parent company four different ways.
Every value receives a key representing the entity behind the text rather than the characters themselves. Records sharing a key are grouped into clusters, which makes each match auditable instead of something to take on faith, and the keys join straight back to your tables.
All of them. Amazon RDS and Aurora, Supabase, Neon, Azure Database for PostgreSQL, Google Cloud SQL, Heroku Postgres, and self-hosted servers are supported on every current PostgreSQL version. Tables, views, and read replicas can all be matched. If the database accepts a standard PostgreSQL connection, the wizard can read from it.
No. Processing issues SELECT statements against the table and columns you choose and nothing else. Nothing is written, updated, or deleted, and no tables, extensions, or functions are created. Results are returned to your browser, and you decide what to do with them.
No. Interzoid connects directly to your PostgreSQL database and reads the columns you select. There is no CSV export, no staging area, and no copy of your data to secure, track, or delete afterward.
The wizard signs in the same way every major data integration tool does: a PostgreSQL username and password over a TLS-encrypted connection. Credentials are sent to Interzoid over HTTPS only when a request is made and are never stored by Interzoid. Because processing is read-only, the recommended practice is a dedicated read-only role that can be dropped at any time.
Yes, with a small change on your side. Add Interzoid's outbound addresses, listed in the documentation, to your database's security group, firewall rules, or authorized networks. Interzoid connects from fixed addresses, so the rule is narrow and can be removed at any time.
Yes. When you choose a table, the wizard counts its rows and shows the number of records and the estimated credits alongside your current balance, before you click Run.
Each record processed consumes one Interzoid API credit. Trial credits are included with a new API account, so a first table can be matched at no cost, and high volume tables are supported for production workloads.
Yes. The same processing is available as a REST API that can be called from scripts, applications, and data pipelines, which allows PostgreSQL matching jobs to be automated without using the browser wizard.
Generate your first match report in minutes. No installation, no code, no changes to your data.
Questions? Contact our team at support@interzoid.com